Looking backward
What have we gotten wrong? Audits of past practice: pitfalls, broken evaluations, threat models that didn’t hold, and the negative results that never got published.
1st Workshop on Meta-Science in AI Security Research
“The first principle is that you must not fool yourself — and you are .”
Why a mirror
Our community has made real progress, and much of it came from refusing to take claims at face value. Yet defenses that looked robust have repeatedly fallen to adaptive attacks. Privacy evaluations have measured the average case when the worst case was the point. Datasets have carried biases and label errors into reported results. Small slips like these can go unnoticed all the way from data collection to the conclusions in a paper.
In most fields, a slip like that is just a wasted result. In security, adversaries go looking for any gap between claimed and actual robustness, so the slip becomes a false sense of security. Other sciences have long studied how incentives and habits shape which findings get published and trusted. AI security is starting to ask the same questions, mostly in scattered papers. MIRROR is a place to ask them together.
What have we gotten wrong? Audits of past practice: pitfalls, broken evaluations, threat models that didn’t hold, and the negative results that never got published.
How do we get it right the first time? Evaluation protocols, reproducible artifacts, data and label quality, and responsible disclosure, built in before mistakes happen.
How do we actually do research? Finding signal in a flood of papers, communicating ideas clearly, and the changing role of LLMs in ideation, writing, and peer review.
Moments of reflection
Topics of interest
Common pitfalls across the ML pipeline, and those specific to individual domains.
Artifact availability, dataset and benchmark decay, reproducibility crises in trustworthy ML.
Defining realistic and tight threat models; adaptive attacks.
LLM reliability, LLM-assisted experimentation and review, pitfalls unique to LLM-centric research.
The value, and under-publication, of failed defenses, null results, and non-replications.
Ethical review processes tailored to adversarial and security research.
Sampling bias, label inaccuracy, spurious correlations, dataset transparency.
Positions on what security research should focus on.
Reviewer incentives, novelty bias, and reforming review in security venues.
Using AI reliably in review, and detecting its misuse.
What ML security can learn from meta-research in clinical trials, systems research, HCI, and beyond.
Where to look for ideas, deciding what matters in a sea of papers, presenting work.
Call for lightning talks
Then you already have a talk. MIRROR invites short talks that surface observations, pitfalls, positions, or lessons learned, so the community can learn from them before repeating them. Early-career and senior researchers, industry practitioners, reviewers, and policy makers are all welcome.
Already published a paper on one of these topics? You’re welcome to submit an abstract about it too.
Important dates
Program
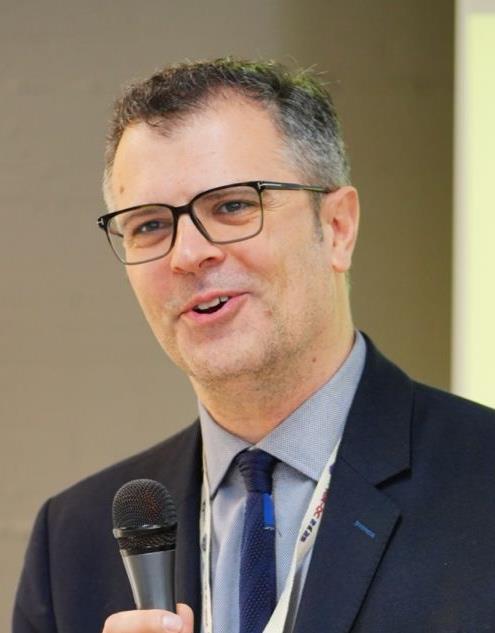
Keynote
University of Cagliari, Italy
Talk title to be announced
Battista Biggio is a Full Professor at the University of Cagliari, research co-director of sAIferLab, and co-founder of Pluribus One. His team was among the first to formalize attacks on machine learning models as optimization problems and to demonstrate evasion and poisoning attacks against them. His paper Poisoning Attacks against Support Vector Machines received the 2022 ICML Test of Time Award, and his Wild Patterns papers looked back on a decade of adversarial machine learning, an early example of the field reflecting on itself. He is an IEEE Fellow and an IAPR Fellow.
Times are local Reykjavík time (UTC+0).
Organizers
CISPA Helmholtz Center for Information Security
University of Vienna & SBA Research
TU Wien
CISPA Helmholtz Center for Information Security