Looking backward
What have we gotten wrong? Audits of past practice: pitfalls, broken evaluations, threat models that didn’t hold, and the negative results that never got published.
1st Workshop on Meta-Science in AI Security Research
“The first principle is that you must not fool yourself — and you are .”
Why a mirror
Our community has made real progress, and much of it came from refusing to take claims at face value. Yet defenses that looked robust have repeatedly fallen to adaptive attacks. Privacy evaluations have measured the average case, leaving the most vulnerable samples unprotected. Datasets have carried biases and label errors into reported results. Small slips like these can go unnoticed all the way from data collection to the conclusions in a paper.
This is not unique to ML: meta-science across the sciences has long examined how pressures such as the push for positive results, novelty-driven reviewing, and little reward for sharing code or replicating others’ work shape which findings get published and trusted. But it weighs heavily in security, where adversaries actively probe any gap between claimed and actual robustness, and an overlooked flaw gives a false sense of security. MIRROR creates a dedicated space for reflecting on our own practices in AI security: a place to share observations, past mistakes, and calls for better practices.
What have we gotten wrong? Audits of past practice: pitfalls, broken evaluations, threat models that didn’t hold, and the negative results that never got published.
How do we build rigor in from the start? Evaluation protocols, reproducible artifacts, data and label quality, and responsible disclosure, so that today’s work doesn’t become tomorrow’s cautionary tale.
How do we actually do research? Finding signal in a flood of papers, communicating ideas clearly, and the changing role of LLMs in generating ideas, writing, and peer review.
Moments of reflection
Topics of interest
Common pitfalls across the ML pipeline, and those specific to individual domains.
Artifact availability, dataset and benchmark decay, reproducibility crises in trustworthy ML.
Defining realistic and tight threat models; adaptive attacks.
LLM reliability, LLM-assisted experimentation and review, pitfalls unique to LLM-centric research.
The value, and under-publication, of failed defenses, null results, and failed replications.
Ethical review processes tailored to AI security research.
Sampling bias, label inaccuracy, spurious correlations, dataset transparency.
Positions on what security research should focus on.
Reviewer incentives, novelty bias, and reforming review in security venues.
Using AI reliably in review, and detecting its misuse.
What ML security can learn from meta-science in clinical trials, systems research, HCI, and beyond.
Where to look for ideas, how to decide what matters in a sea of papers, and how to present your work.
Call for lightning talks
Then you already have a talk. MIRROR invites short talks that surface observations, pitfalls, positions, or lessons learned, so the community can learn from them before repeating them. Early-career and senior researchers, industry practitioners, reviewers, and policy makers are all welcome.
Already published a paper on one of these topics? You’re welcome to submit an abstract about it too.
Important dates
Program
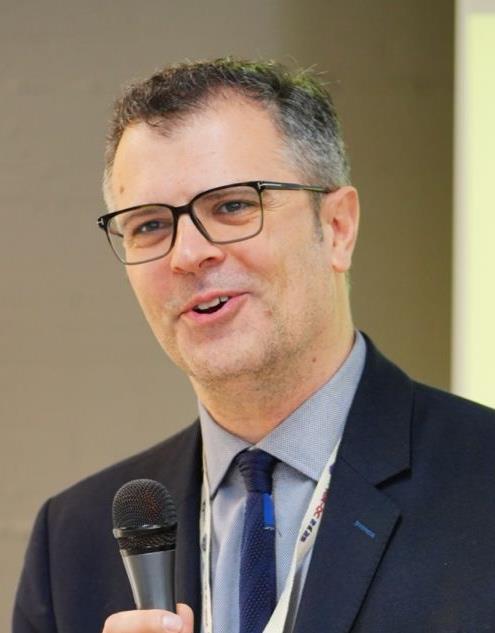
Keynote
University of Cagliari, Italy
Talk title to be announced
Battista Biggio is a Full Professor at the University of Cagliari, Italy, research co-director of sAIferLab, and co-founder of Pluribus One. A pioneer of AI security, he and his team were the first to formalize attacks on machine-learning models as optimization problems and to demonstrate evasion and poisoning attacks against them, playing a leading role in the establishment and advancement of the research field. His paper Poisoning Attacks against Support Vector Machines received the 2022 ICML Test of Time Award. His review Wild Patterns: Ten Years After the Rise of Adversarial Machine Learning, one of the earliest works to reflect on the field as a whole, received the 2021 Best Paper Award and Pattern Recognition Medal from Elsevier’s Pattern Recognition.
Times are local Reykjavík time (UTC+0).
Organizers
CISPA Helmholtz Center for Information Security
University of Vienna & SBA Research
TU Wien
CISPA Helmholtz Center for Information Security